MJorgin/dsh-media-skills
Free vision & image generation for DeepSeek Harness — paste an image into any chat, even text-only sessions. GLM-4V-Flash / Qwen3-VL / Gemini failover chain, ModLens-style structured evidence, Kolors generation. 免费读图·生图 · 三引擎容错 · 无 Key 入库
Listed
8
Vision
Bundle verified
Preview
What it does
Free vision bridge and image generation for text-only models: paste-image reading, GLM-4V-Flash and Gemini engine failover, ModLens-style structured evidence, and a seeded free vision model route.
Best for
- Users of text-only DSH models who need pasted images or screenshots converted into textual evidence.
- Visual review workflows that need structured image analysis with failover across supported vision providers.
- DSH users who want image generation alongside image-reading skills.
- Users who want a free vision-model route added to the model selector.
Not ideal for
- Offline or strictly local image workflows, because images are sent to the provider selected by the user.
- Users unwilling to obtain and configure provider API keys; the bundle does not supply hardcoded shared keys.
- Paste-image workflows on the documented rc.7/rc.8 Harness path when the required core api-proxy admission patch is unavailable.
- Environments without Python 3.9 or newer.
README

🎨 dsh-media-skills
Give DeepSeek Harness eyes — and a brush. Read images in any chat, generate new ones, all with free models.


DeepSeek Harness is brilliant at reasoning — but a text-only model can’t see the image you just dragged into the chat. This bundle fixes that with two free skills, a free vision model route, and a vision engine failover chain:
- 📎 Paste to read — paste, drag, or pick an image in any session; the free vision model turns it into text your current model understands. (Powered by the DeepSeek Harness core auto-description path — see docs/HARNESS_PATCH_EN.md; this bundle contributes the vision model route and the skill it relies on.)
- 👁️
vision-review— analyze images and screenshots, catch UI visual bugs, detect watermarks, turn images into text. - 🎨
media-tools— generate illustrations, avatars, backgrounds and banners with a free, watermark-free model. - 🔀 Engine failover — GLM-4V-Flash → SiliconFlow Qwen3-VL → Google Gemini (AI Studio) → any OpenAI-compatible endpoint, with ModLens-style structured evidence output.
No hardcoded keys, no paid API, no file saving, no session switching.
Why · Quick start · See it in action · Usage · Keys & privacy · FAQ · Examples
English · 简体中文 · 繁體中文 · 日本語 · 한국어 · Español · Deutsch · Português · Русский
🤔 Why
Most DSH vision plugins only read images — and many push you through a shared third-party endpoint. dsh-media-skills takes a different stance:
| This bundle | Typical vision-only plugin | |
|---|---|---|
| Read images for free | ✅ Zhipu GLM-4V-Flash | ✅ |
| Generate images for free | ✅ SiliconFlow Kolors | ❌ usually absent |
| Auto model route in the picker | ✅ installed automatically | sometimes |
| Keys committed to the repo | ❌ never — keys stay local | ⚠️ often required |
| Docs in multiple languages | ✅ 9 languages | ❌ usually English only |
| Privacy | ✅ you choose the provider; images only go to your provider | shared free endpoints can see your images |
Why bring your own free key instead of a built-in anonymous endpoint? Privacy and reliability. Your images go only to the provider you choose, under your account and your rate limits — no shared third-party service in the middle.
✨ What you get
| Capability | What it does | Model | Cost |
|---|---|---|---|
| 🖼️ Paste-image reading | In a text-only session, paste, drag, or pick (add-image button, restored by the client-ux patch) an image into the composer; it is described by the vision model (GLM-4V-Flash with SiliconFlow Qwen3-VL failover, 15s per route) and handed to the current model as text beside a live thumbnail. (Harness-core feature on rc.7/rc.8: requires the api-proxy admission patch + the rc.8 client-ux patch — see docs/HARNESS_PATCH.md / HARNESS_PATCH_EN.md, both patch files included for rc.8; this bundle supplies the vision route + skill it depends on) | GLM-4V-Flash + Qwen3-VL | Free |
| 🧠 Vision model route | 「智谱 GLM-4V-Flash(视觉)」 appears in the model selector automatically — pick it for a new conversation and talk about images directly | Zhipu GLM-4V-Flash | Free |
👁️ vision-review
|
Analyze / recognize / describe images & screenshots; catch UI visual bugs (overlap, overflow, misalignment); detect watermarks/logos; turn images into text. Optional --structured mode returns ModLens-style evidence JSON (summary, full OCR, reading-order layout, entities/relations, uncertainty). Engine failover chain: GLM-4V-Flash → SiliconFlow Qwen3-VL / Google Gemini (auto-join with free keys) → any OpenAI-compatible endpoint |
GLM-4V-Flash + Qwen3-VL + Gemini | Free |
🎨 media-tools
|
Generate images, illustrations, avatars, backgrounds, banners | SiliconFlow Kolors | Free, no watermark |
⚡ Quick start
dsh plugin --profile <name> add github:MJorgin/dsh-media-skills
-
Get two free keys (~2 minutes, no payment):
- Zhipu — open.bigmodel.cn → API Keys (
glm-4v-flashis free) - SiliconFlow — siliconflow.cn → API Keys (Kolors is free)
- (optional third) Google Gemini — aistudio.google.com → Get API key; joins the vision failover chain automatically
- Zhipu — open.bigmodel.cn → API Keys (
-
Add them in the Web GUI (Settings → Models → the zhipu-vision provider’s API Key field), or use the credentials file:
# ~/.dsh/.credentials.yaml (chmod 600) GLM_API_KEY: <your key> -
Restart
dsh web, then hard-refresh (Cmd+Shift+R).
Verify: the model selector shows 智谱 GLM-4V-Flash(视觉). If your Harness build supports paste-image reading, the input bar also has a 📎 Add image button — paste an image in any session and it arrives as a text description.
Full walkthrough and troubleshooting: docs/SETUP_VISION_EN.md.
📸 See it in action
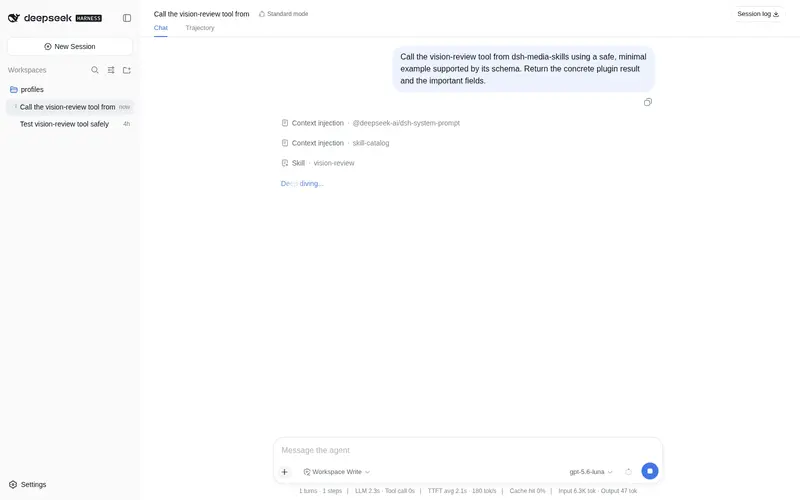
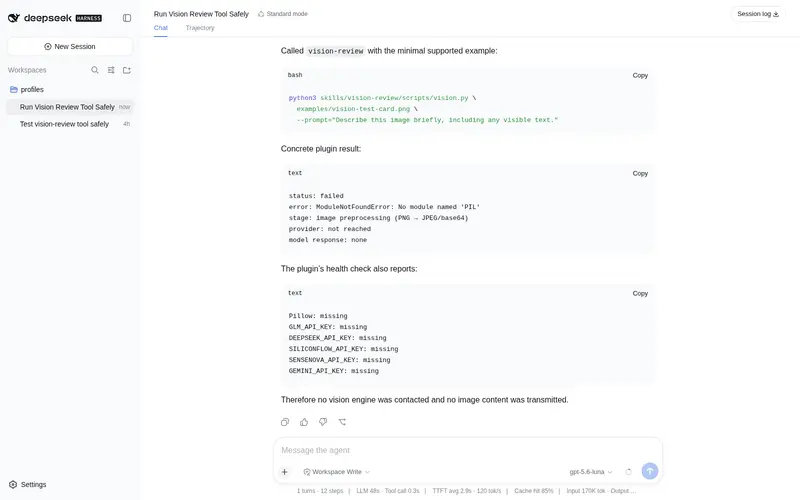
Paste an image in a text-only session → the free vision model describes it → your model answers. The same bundle also generates new images on demand.

How it works in one picture:

🚀 Usage
Three ways to read images:
| Way | How | When |
|---|---|---|
| A. Paste directly (recommended) | In any session, click the 📎 button / drag / paste an image and send | Everyday image questions — no file saving, no model switching |
| B. Vision model session | New conversation, pick 智谱 GLM-4V-Flash(视觉), paste images and chat | Multi-turn image conversations, native read_image
|
| C. Files + skill | Put the image in the workspace and say “read this image with vision-review” | Batch review, scripted workflows |
Descriptions follow your message language (Chinese message → Chinese description; English message → English description; no text → Chinese).
Also just say:
- “Look at this image / check this screenshot for visual bugs” →
vision-review - “Generate an image of …” →
media-tools
🔑 Keys & privacy
Keys are never stored in this repo. Skill scripts read, in order: environment variables → ~/.dsh/secrets/media-tools.env → ~/.codex/secrets/media-tools.env (legacy fallback). The vision model route reads GLM_API_KEY from DSH’s credential store.
Where to get the keys (all free): Zhipu — open.bigmodel.cn → API Keys (glm-4v-flash). SiliconFlow — siliconflow.cn → API Keys (Kolors). Google (optional, joins the vision failover chain automatically) — aistudio.google.com → Get API key.
# ~/.dsh/secrets/media-tools.env (chmod 600, one KEY=value per line)
GLM_API_KEY=...
SILICONFLOW_API_KEY=...
GEMINI_API_KEY=...   # optional
Your images are sent only to the provider you configure — never to this repo, never to a shared anonymous endpoint.
Privacy note on Gemini: Google’s free-tier key comes with data-use terms — requests may be used to improve Google products. For sensitive images (IDs, internal docs, customer data), prefer the direct domestic engines (Zhipu / SiliconFlow).
❓ FAQ
Does paste-image reading require a DeepSeek Harness core patch?
The auto-describe pipeline lives in the Harness core (api-proxy image-admission logic; see docs/HARNESS_PATCH_EN.md). This bundle ships the model route + skills: the vision model works on any DSH build, but paste-image reading requires a Harness build with that core support — see FAQ Q1 in docs/SETUP_VISION_EN.md.
Why not just use a built-in free endpoint with no key at all? We prefer to let you own the route: your images go to the provider you pick, under your rate limits, with no shared middleman. The keys are free and take about two minutes to create.
Is media-tools really free?
Yes — SiliconFlow Kolors is free and watermark-free. If a model is temporarily disabled, the skill lists available models and you can switch.
🎁 Examples
Sample material to try instantly — 6 AI-generated images with their prompts, plus a purpose-built vision test card (title, buttons, bar-chart values) for checking reading accuracy:


🗺️ Layout
dsh-media-skills/
├── package.json           # dsh.bundle manifest
├── cordis.patch.yml       # plugin layer
├── index.js               # registers skills + seeds the zhipu-vision model route
├── skills/
│   ├── vision-review/     # image reading
│   └── media-tools/       # image generation
├── examples/              # sample images + vision test card
├── docs/
│   ├── screenshots/       # demo mockup & how-it-works diagram
│   ├── SETUP_VISION_EN.md # detailed setup guide (English)
│   ├── SETUP_VISION.md    # 详细配置指南(中文)
│   ├── HARNESS_PATCH_EN.md# core patch notes (English)
│   ├── HARNESS_PATCH.md   # 本体补丁说明(中文)
│   ├── COMPARE_MODLENS.md # 与 ModLens 的对比/共存(中文)
│   └── lang/              # READMEs in 9 languages
├── scripts/make-banner.py # regenerates docs/social-preview.png
└── docs/social-preview.png
🧩 Using ModLens alongside?
Both this bundle and ModLens give text-only models vision. Installed together they do not conflict: ModLens intercepts pastes first (path → modlens_read_image tool), and this bundle’s api-proxy fallback handles anything it doesn’t take over. See docs/COMPARE_MODLENS.md (中文) for the full comparison, the paste routing order, and how to point ModLens at the same free Zhipu endpoint.
🤝 Join the DSH plugin ecosystem
DeepSeek Harness developer preview is still in its testing phase for Harness developers; core plugins and base APIs will keep iterating. We look forward to exploring the upper limits of intelligence together with developers worldwide, on top of open-source, open, reusable, and composable infrastructure.
- dsh-plugin topic
- Quickstart
- DeepSeek Harness repo
- dsh-agent-conductor — 同作者的指挥家:在 DSH 里派活给 11 种外部 agent CLI(Codex / Claude Code / TraeCode…)
This repo is tagged
dsh-pluginand listed in the awesome-dsh-plugin curated list. PRs, issues and translations are welcome.
📄 License
Frequently Asked QuestionsFAQ
Use the verified command dsh plugin --profile default add github:MJorgin/dsh-media-skills in a DSH-enabled shell. The command resolves the public package metadata and keeps the plugin attached to the catalog identity shown on this page.
Compatibility follows the bundle and profile status shown above. If a profile is not detected, keep the plugin disabled there and check the repository documentation before enabling it in production.
The GitHub link and activity metadata are the source of truth for releases and maintenance. Revisit this page after a new release to confirm the catalog has observed the latest version.